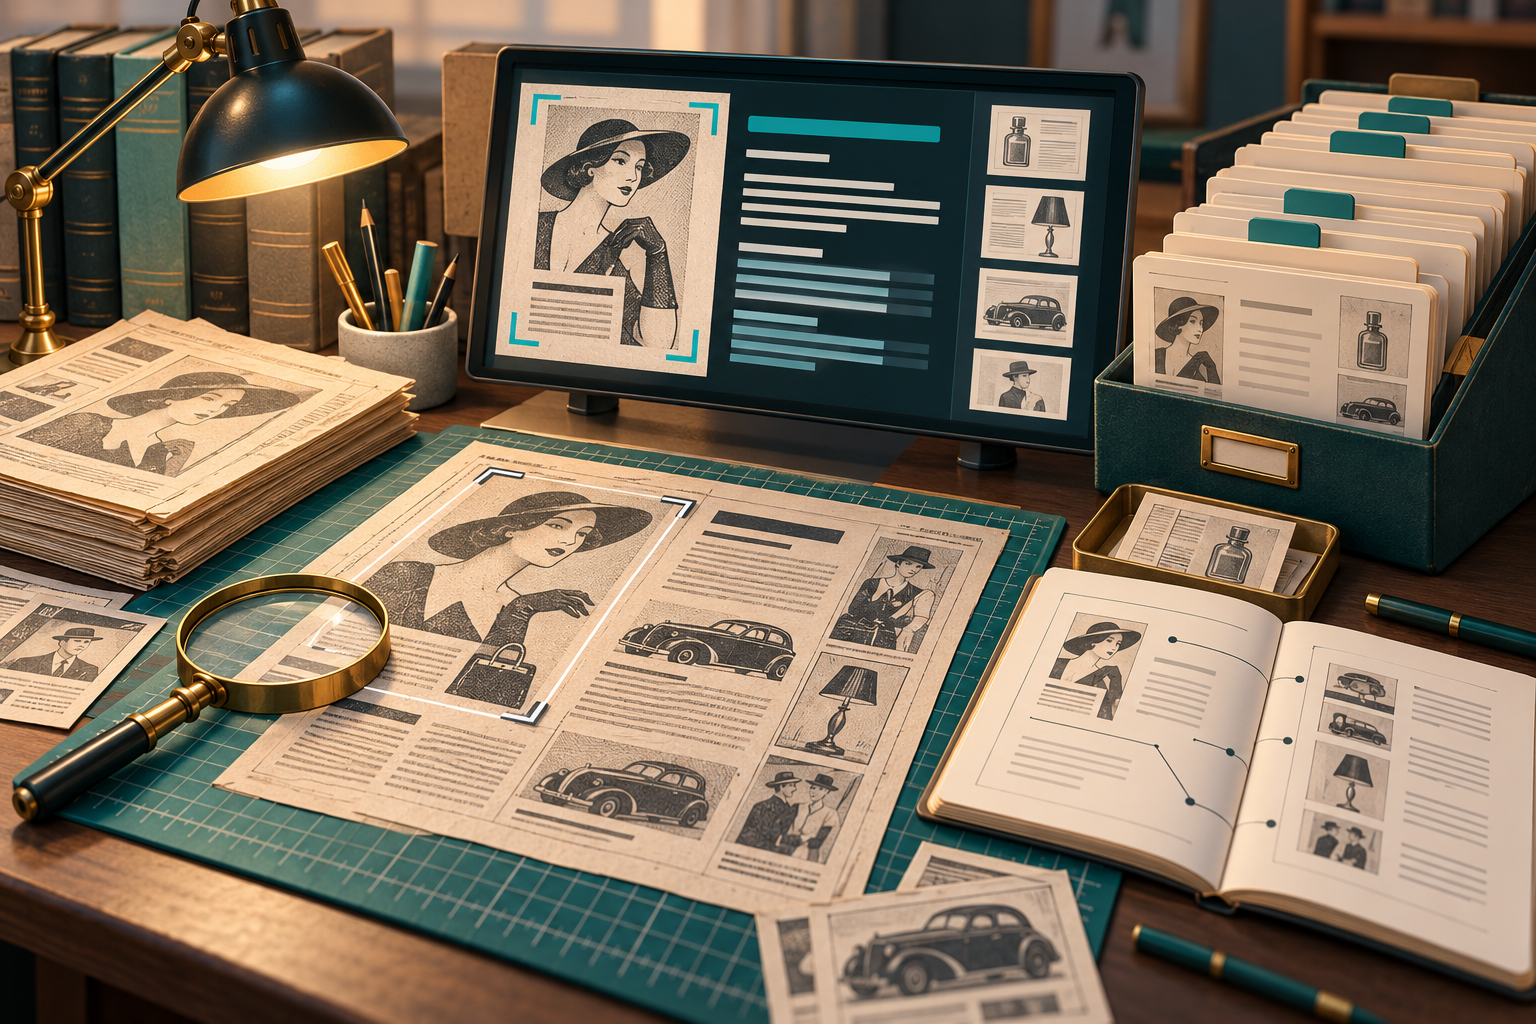
From a document page to an advertisement record
Old Ads, named Reklame Detektiven in the application, is structured around investigating advertisements in historical documents. Its backend separates documents, advertisement records, advertisers, collections and media rather than treating every uploaded page as an isolated image.
The inspected source includes detection, OCR, pipeline and training modules. These provide a foundation for combining automated extraction with an organized research interface.
Connected archival tasks
- Source-document and media management.
- Page and crop processing.
- Advertisement and advertiser records.
- Collection-level organization.
- Detection/OCR tooling and a training area.
A source-based overview
The frontend package uses Vue and Vite, while FastAPI exposes domain routers and a WebSocket update mechanism. The root README is minimal, so the overview is based on inspected architecture rather than a detailed release specification.
No claim of universal OCR accuracy, complete historical coverage or unrestricted source-image rights is made. The featured illustration uses invented vintage layouts and is not copied from the project's document collection.
Project notes
This overview was prepared from a private project repository reviewed on October 29, 2026. Source access remains private; credentials, internal endpoints and confidential implementation details are not included.