From public sources to reusable datasets
OpenData brings together collection scripts, structured outputs and documentation for Danish open data. It is the working collection behind a range of reusable resources, with attention to provenance and the transformations needed to turn source material into practical files.
What the collection covers
- Danish word lists, spelling and grammatical resources derived from COR.
- Baby-name data and historical statistics, including alcohol and tobacco consumption.
- A catalog of Danish public data sources and standardized CSV, JSON and text outputs.
Working collection and distribution
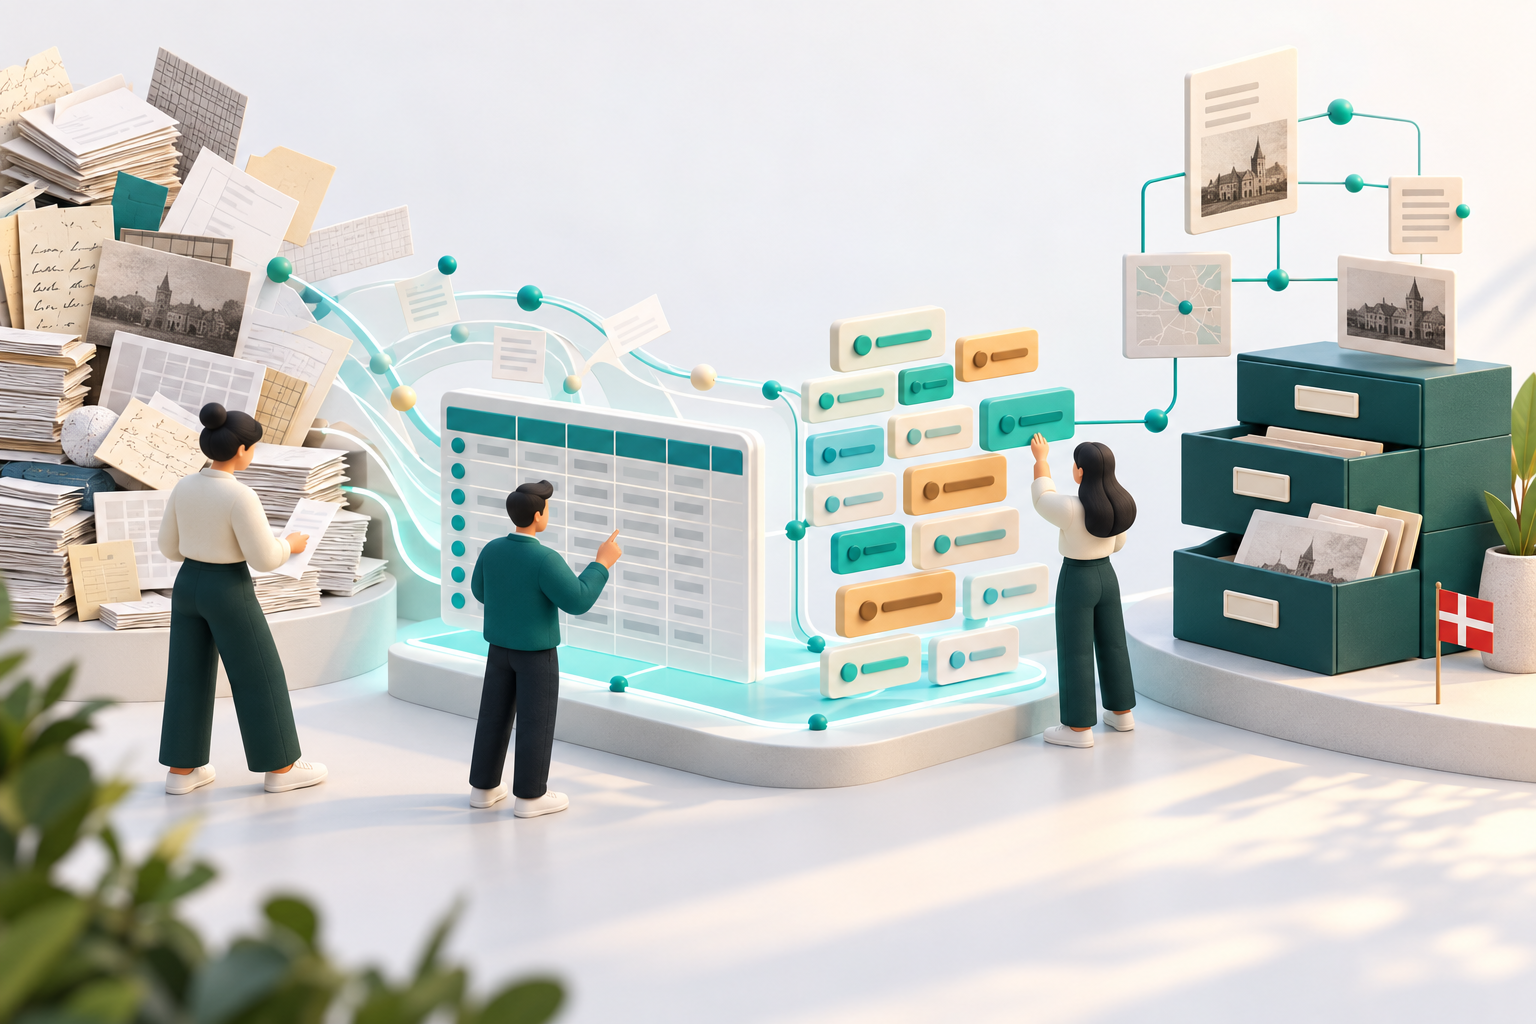
Collection and processing belong here; the separate OpenDataSets project distributes selected datasets, while OpenDataMCP makes selected resources available through tools. Reuse conditions depend on the individual dataset: some resources use CC0, while Statistics Denmark material requires attribution under CC BY 4.0. The illustration represents a data workflow rather than a view of the actual collection.
Project notes
This overview was prepared from a private project repository reviewed on October 29, 2026. Source access remains private; credentials, internal endpoints and confidential implementation details are not included.